NOVAKI
> reads the logs so you don't have to
AI coding agents and models, tested head to head. Same prompts, blind judges, real bills.
- YouTube@Novaki_ai · AI models, tested head to head
- X@Novaki_ai Instagram@novaki_ai
- The match wall21 AI settings drew the same burning match
- The arenaSame prompt, five models, every run recorded
- ScoreboardWho won, and what it cost
- This week in AITen stories worth knowing, with sources
-
Meet NovakiThe matchstick behind the channel
NOVAKI · EST. 2026
From the effort test · 84 runs
Twenty-one settings drew the same match.
Claude Opus 5.5, Claude Haiku 5.5, GPT-6.1 Sol and GPT-6 Luna got one job at every effort level they offer: draw a wooden match that lights itself, burns and goes out. All 21 worked. Here they are, running.
Claude Haiku 5.5 · medium
$0.018
Claude Opus 5.5 · max
$4.75
Same score. 259× the price.
the expensive setting lost
How the matches were scored
Gemini 4 Argon test · 150 runs
Same prompt. Five models. Every run on tape.
Gemini 4 Argon, GPT-6.1 Sol, GPT-6 Astra, Claude Opus 5.5 and Claude Sonnet 5.5 each worked inside their own coding agent at low, medium and high effort. Same ten prompts, tools off. These are the recordings the judges scored.
Names are hidden and rows are shuffled. Click the result you like best.
Read the exact prompt
The other six tests
The snake games were played by a robot. The two functions met hidden test suites. The puzzles and trick questions had one right answer each.
Final scoreboard · out of 10
Close at the top. Not close on price.
Each score is the average of ten tests at three effort levels. Cost is all 30 runs at API prices; time is wall-clock time, added up.
All 150 runs, one square each
Brighter means a higher score. Hover or tap a square for the details.
How Novaki tests
The rules don't change between models.
-
1
Same job for everyone
Every model gets the same prompt, the same starting files and the same settings, with tools turned off. Claude Code loads your personal CLAUDE.md by default, so we turned that off and reran all 60 Claude runs.
-
2
Every effort level
Low, medium and high, plus xhigh, max and ultra where a model offers them. Higher effort means a bigger thinking budget, and a bigger bill. We check whether the score moves with it.
-
3
Judges who can't see names
Visual work is scored from the recorded frames by two judges from two companies, with a fixed rubric. Code meets hidden tests, and a robot plays every game.
-
4
Every run saved, every bill checked
Time is measured on the wall clock. Cost is tokens times each company's API price on the day of the test. Every run is kept, so you can check our math.
On the shelf
Three episodes, ready to strike.
Open a box to look inside. They premiere on the channel soon; subscribe and you'll catch the first one.
This week in AI
The news worth knowing, with receipts.
Every week, the AI stories that matter, each one with its source. This is the week of October 5–11, 2026.
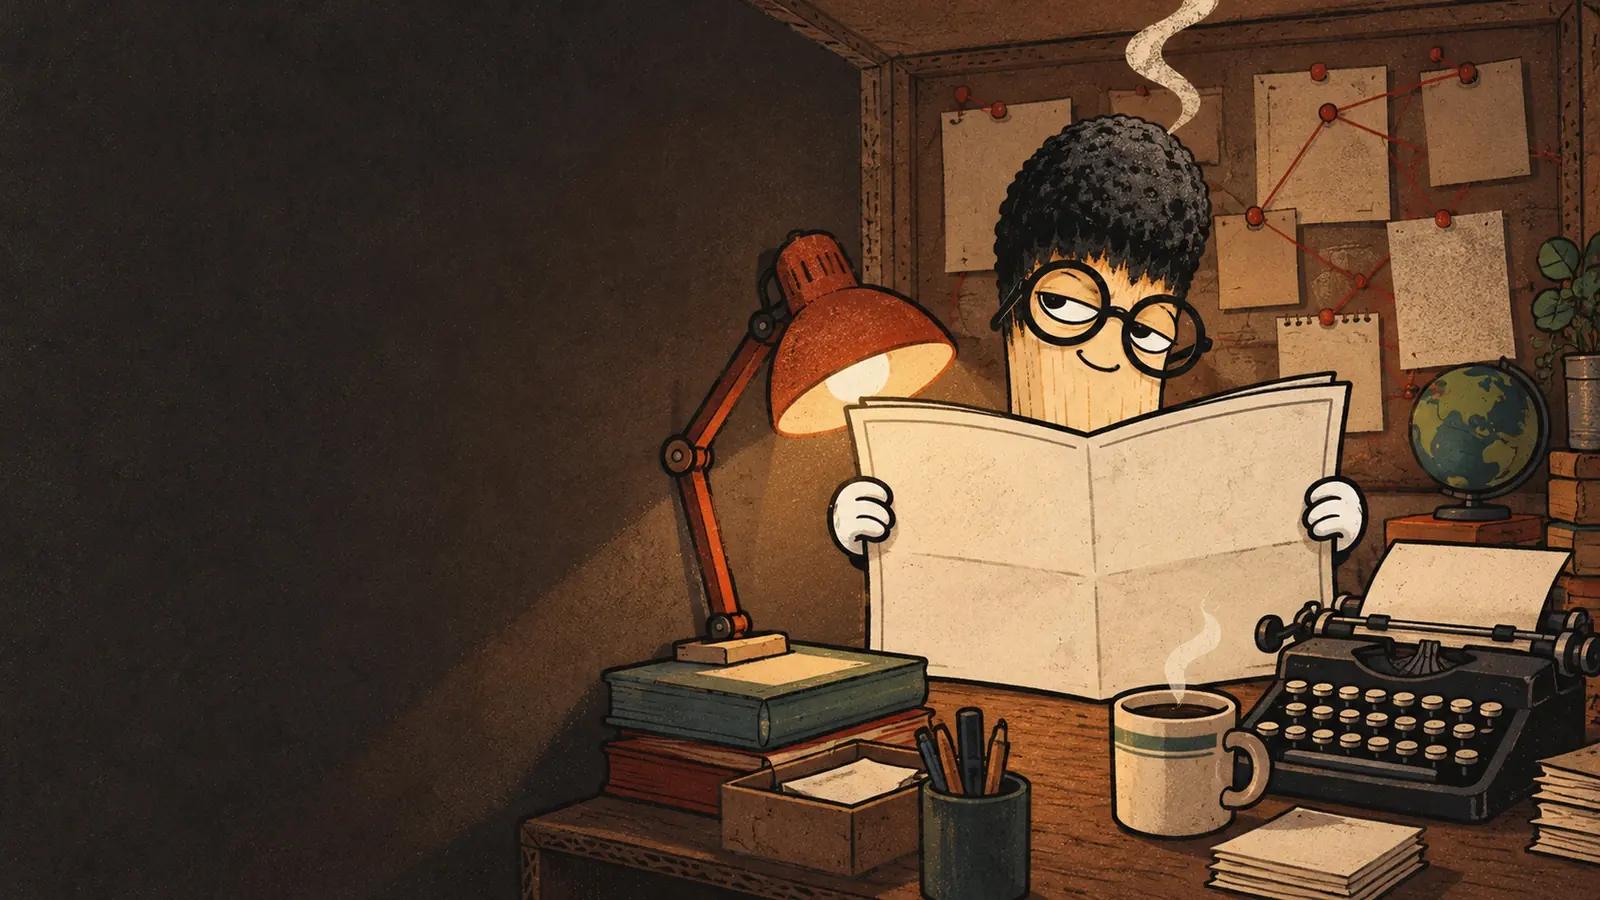
Hello. I read the logs so you don't have to.
Your host
Meet Novaki.
A short, chunky matchstick with a burnt head and crooked glasses. Dry, hard to impress, and very good at reading logs. Pick a mood and watch the smoke.
- Made of
- One chunky wooden matchstick
- Head
- Already burnt. It happens.
- Glasses
- Thick, round, slightly crooked
- Mood gauge
- The smoke. Straight up when calm, a question mark when confused, a little cloud when thinking.
- Afraid of
- Wind, water and max-effort invoices
Side quest
One matchstick, twelve worlds.
Clay, chalk, pixels, felt. Every clip starts from a different drawing style, and Novaki is still Novaki.
House rules
The fine print, in large print.
- Not sponsoredIf that ever changes, the video says so up front.
- AI voice · real numbersThe narration uses an AI voice. The tests, numbers and sources are real.
- Sources listedEvery video lists its sources in the description.
- Blind judgesJudges score the work without knowing which model made it.
- Runs savedEvery run is kept, so a test can be repeated and checked.
Subscribe
Strike
anywhere.
New model tests and a weekly AI news roundup. Same prompts, blind judges, real bills.